Cloud-Native Air Pollution & Respiratory Death Analysis
A cloud data project analysing average PM2.5 pollution and respiratory deaths using Azure and PySpark.
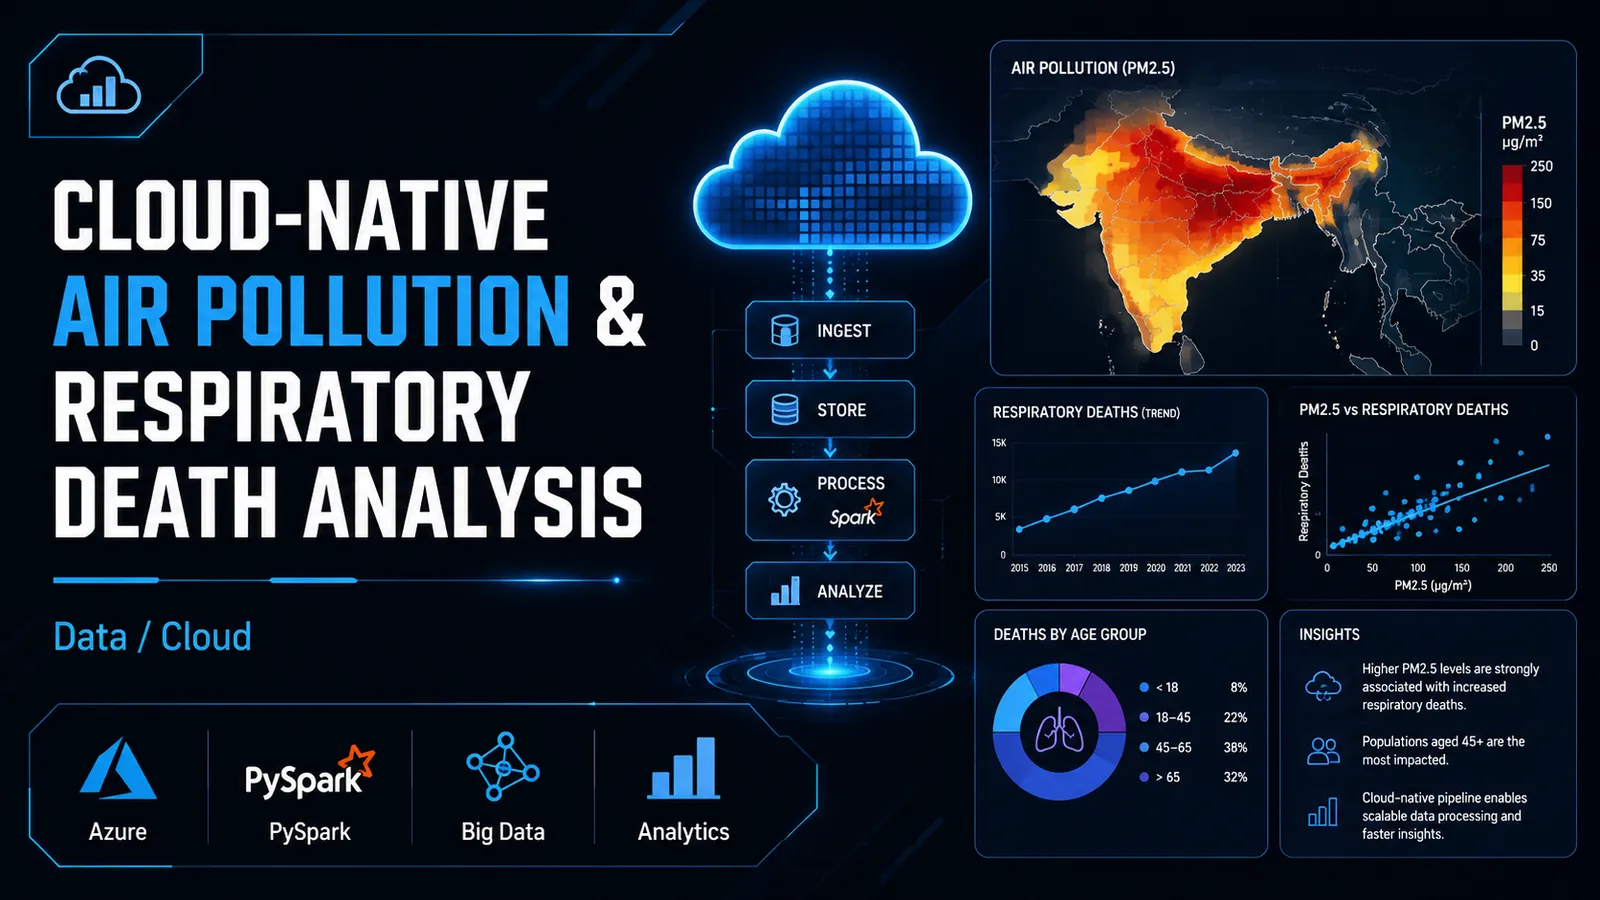
Project Description
This project analyses the relationship between air pollution exposure and respiratory mortality using a cloud-native data processing workflow. It is designed as a public-health analytics system where pollution and mortality datasets are ingested, cleaned, transformed, modelled and visualised through dashboards. WHO identifies ambient air pollution as a major global health issue and estimates millions of premature deaths linked to outdoor air pollution, making this a strong real-world data project.
Problem
Environmental and health datasets are often large, distributed and difficult to interpret. Public-health decision makers need dashboards and analytical pipelines that can connect air quality indicators with respiratory death trends.
Solution
The project proposes a cloud-native analytics architecture using data lake storage, scalable Spark processing, transformed analytical datasets and interactive dashboards. Microsoft Azure Data Lake and Azure Synapse Spark are suitable for this type of scalable cloud data processing.
Main Features
FeatureDescription
Data Ingestion
Imports pollution and mortality datasets
Data Lake Storage
Stores raw and processed datasets
PySpark Processing
Cleans, joins and aggregates data
Analytical Modelling
Compares pollution exposure and health outcomes
Visual Dashboard
Shows trends by location, year and pollutant
Risk Interpretation
Identifies high-risk regions or periods
Documentation Angle
This project should be documented as a cloud data engineering and public health analytics case study. Include architecture diagram, data pipeline, ETL process, dataset table, dashboard screenshots, limitations and ethical use of public health data.